
AI Glossary
LLM-as-a-judge
Also called model-graded evaluation
What does “LLM-as-a-judge” mean?
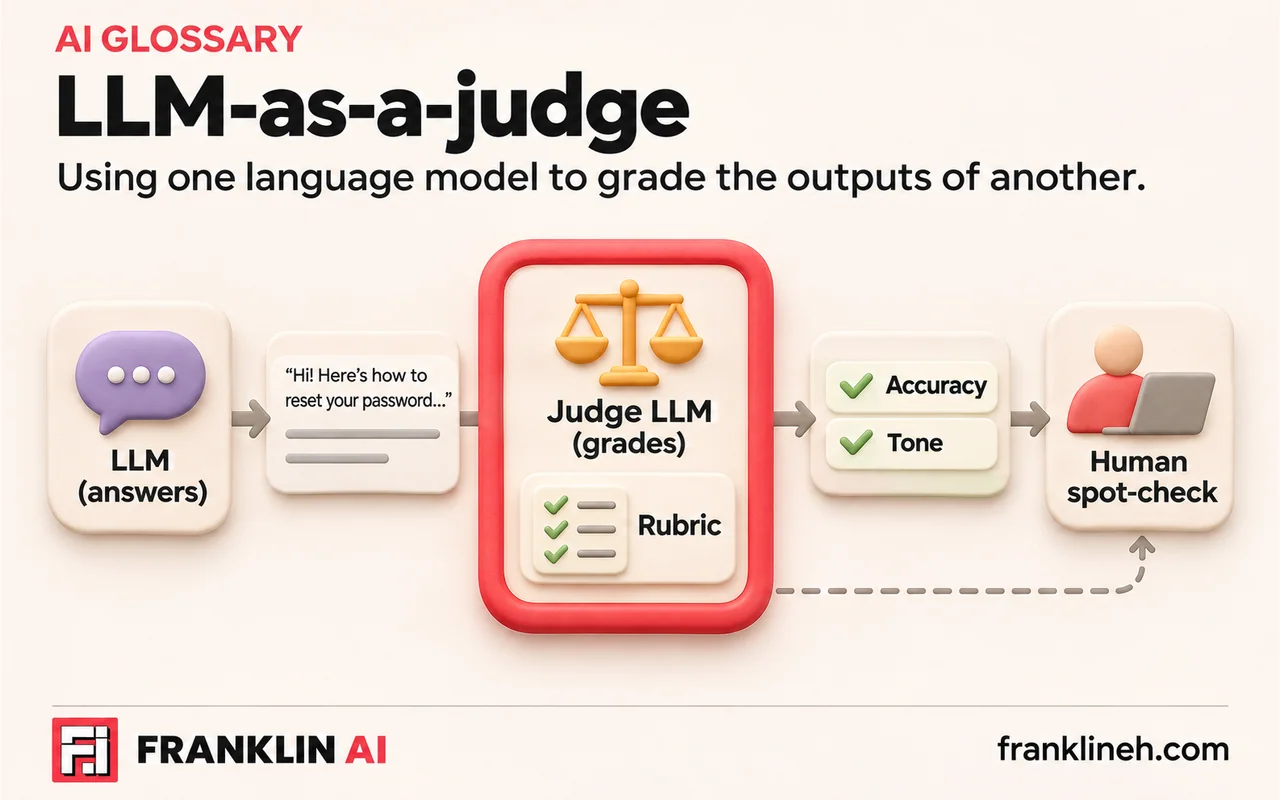
LLM-as-a-judge: Using one language model to grade the outputs of another, typically against a rubric. It makes evaluating open-ended answers, such as essays or chat replies, far cheaper and faster than human review. Judge models have their own biases, including favouring longer answers or their own style, so they are usually checked against human ratings.
What is an example of “LLM-as-a-judge”?
A team might have a model score 10,000 support replies for accuracy and tone, then spot-check a sample with human reviewers.