
AI Glossary
Mechanistic interpretability
What does “Mechanistic interpretability” mean?
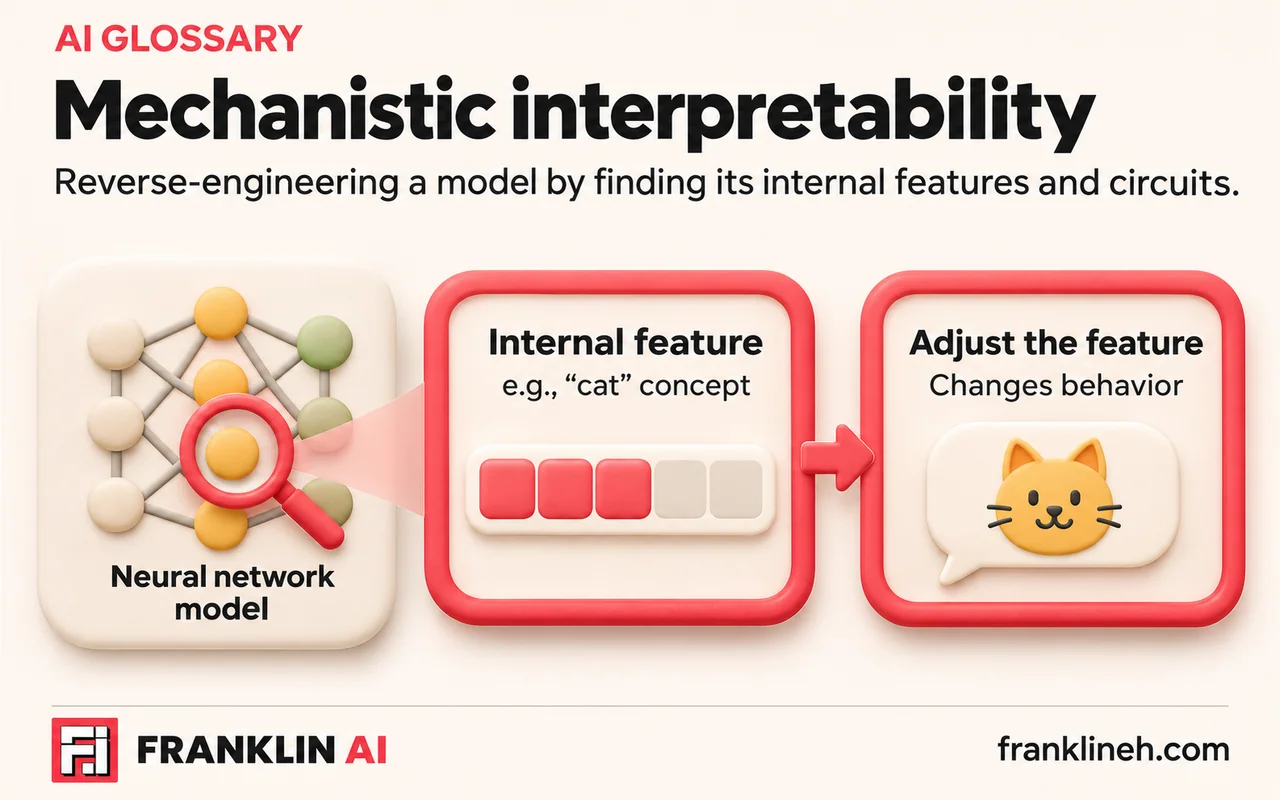
Mechanistic interpretability: Research that tries to reverse-engineer neural networks by identifying the internal features and circuits that carry out specific computations. Instead of explaining behaviour from the outside, it studies the model's activations and weights directly, aiming to understand models well enough to spot deception or hidden goals.
What is an example of “Mechanistic interpretability”?
Researchers have located internal features in language models that activate for specific concepts, and shown that adjusting them changes the model's behaviour.