
AI Glossary
Vision-language model
Also called VLM
What does “Vision-language model” mean?
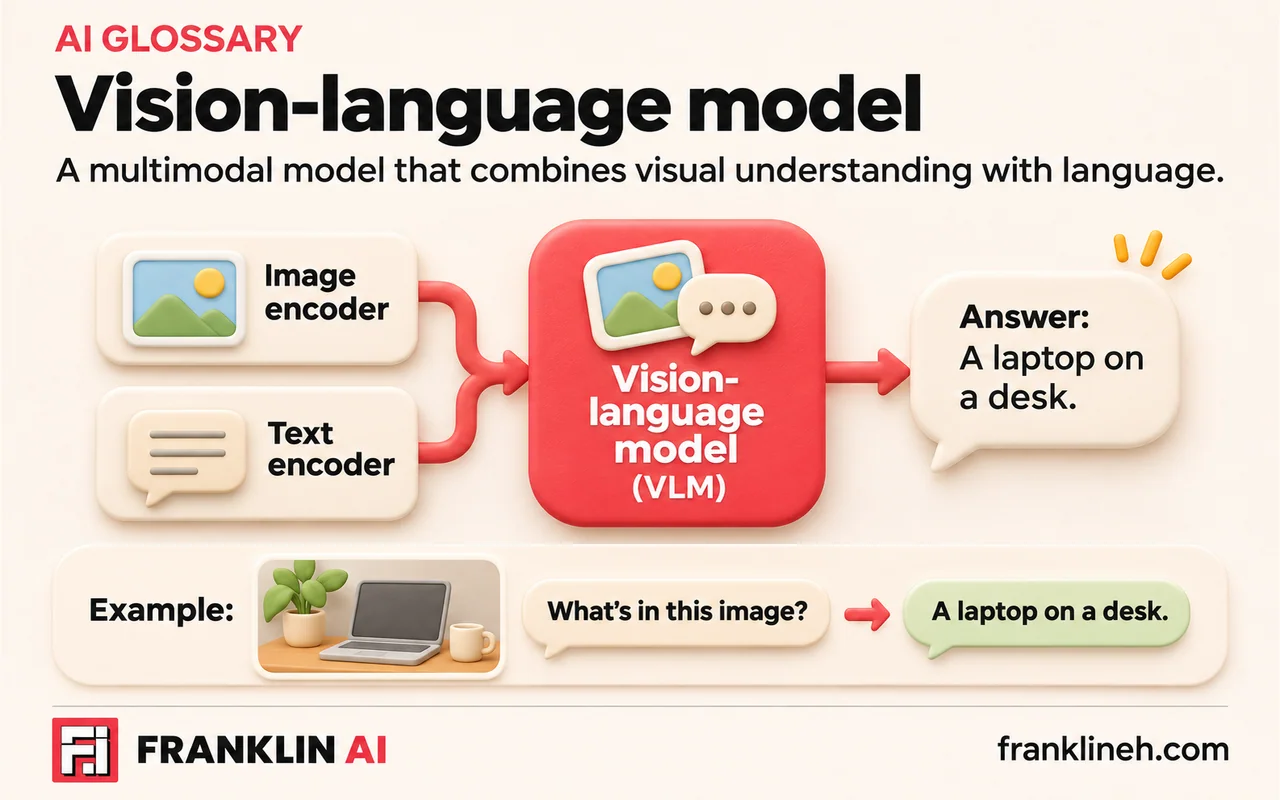
Vision-language model: A multimodal model that combines visual understanding with language. It usually pairs an image encoder with a language model so it can answer questions about images, read text in screenshots, or describe what a scene shows.
What is an example of “Vision-language model”?
Tools that let an AI agent read a web page from a screenshot, or explain a diagram in a textbook, typically rely on a vision-language model.