
AI Glossary
Vision transformer
Also called ViT
What does “Vision transformer” mean?
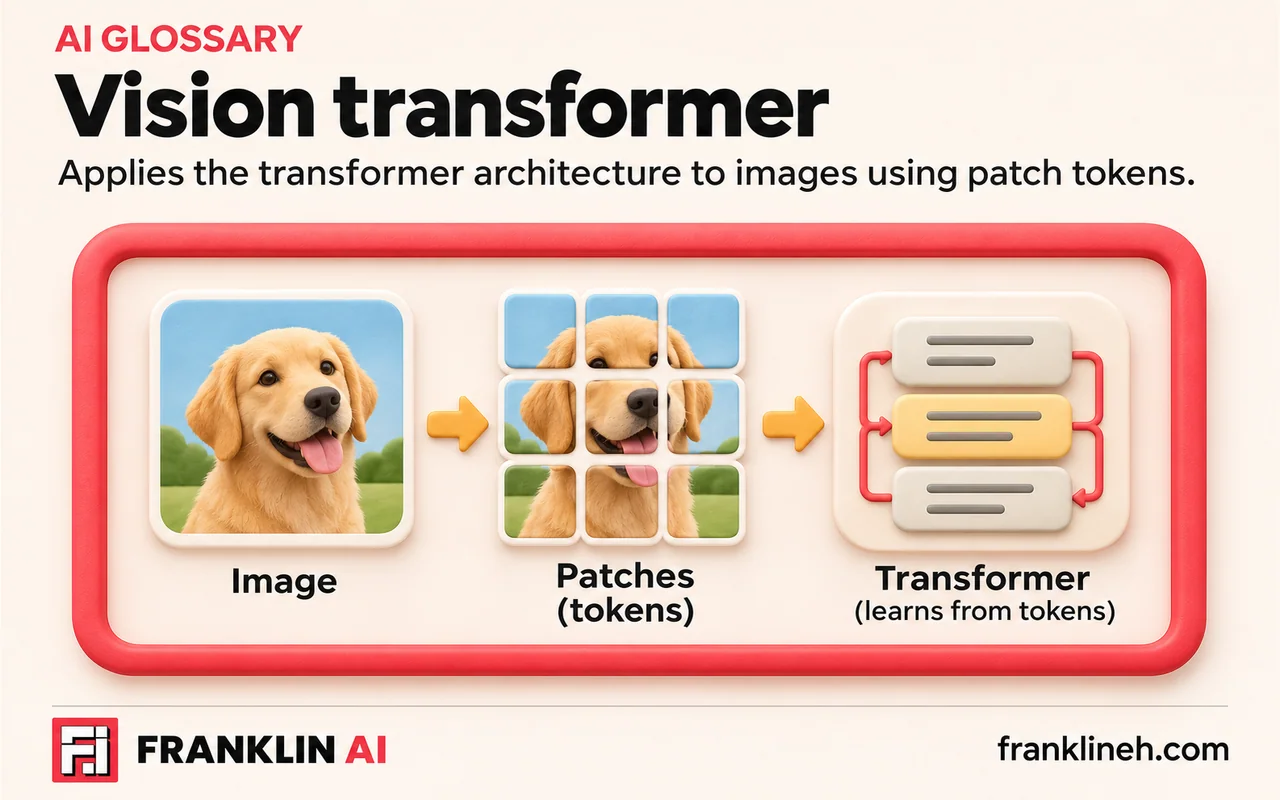
Vision transformer: Applies the transformer architecture to images by cutting each picture into small patches and treating them like a sequence of tokens. Given enough training data, vision transformers match or beat convolutional networks on many vision tasks.
What is an example of “Vision transformer”?
Many vision-language models use a vision transformer as their image encoder, turning a photo into tokens the language model can reason about.