

Apify: Web Data Extraction & Automation
Apify provides a marketplace and execution platform for Actors that collect web data and connect with applications or AI agents.
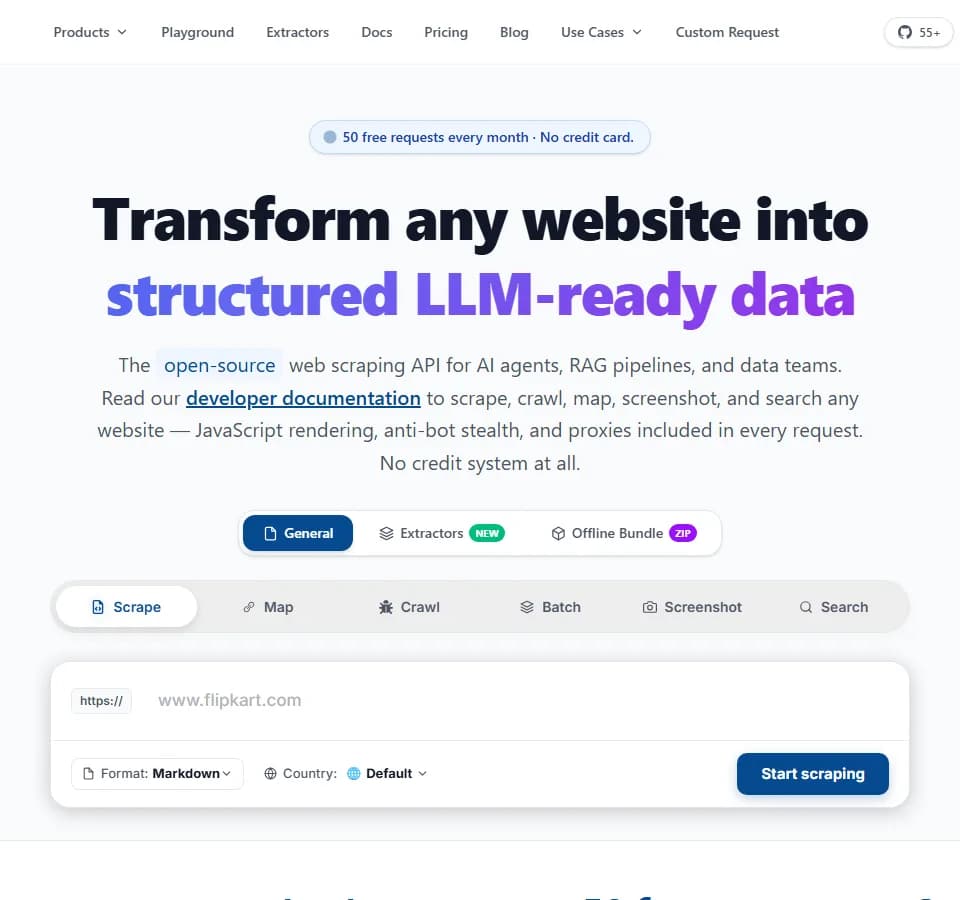
GcrawlAI is an open-source web-scraping API that converts websites into LLM-ready Markdown or JSON with crawling, rendering, search, and screenshot endpoints.
GcrawlAI is an open-source web-crawling and scraping API that converts websites into Markdown, JSON, HTML, metadata, images, and other structured outputs for AI and data workflows. It is operated by Gramosoft Private Limited and is offered as both a hosted service and a self-hostable engine.
GcrawlAI retrieves website content through an API designed for applications that need machine-readable web data. Its scrape endpoint can produce clean Markdown, raw HTML, JSON, SEO metadata, and extracted images. The crawl endpoint discovers and processes accessible subpages, with controls for crawl depth and path filtering, while webhook delivery supports longer-running crawl workflows.
The service also includes endpoints for processing multiple URLs in parallel, discovering site URLs, capturing screenshots, and returning web-search results for agent workflows. The vendor describes the API as suitable for AI agents, retrieval-augmented generation (RAG) pipelines, research, and general data-processing workflows.
GcrawlAI is aimed at developers building agents that need current website content, RAG systems assembling source material, researchers collecting web data, and teams adding structured website extraction to automated workflows. It can also suit organizations that prefer to run the underlying crawling engine themselves rather than rely only on a hosted endpoint.
A typical workflow can send a URL to the scrape endpoint and pass the resulting Markdown or JSON into an agent, search index, or processing pipeline. Larger jobs can use crawl for related pages, batch for multiple URLs, map to discover a site's URL structure, or screenshot when visual page captures are needed. The stated SDKs and integrations are intended to reduce the work of connecting the API to common agent and orchestration frameworks.
Hosted billing is request-based: the vendor states that one request counts as one request regardless of rendering or stealth options, and that failed requests are not counted. The site advertises 50 free requests per month without a credit card and paid plans starting at ₹1,587 per month for 3,000 requests.
The main practical strengths are the range of extraction formats and endpoint types, JavaScript-aware browsing, and the choice between hosted access and self-hosting. The vendor claims that its escalation tiers provide fingerprint-safe extraction, browser cloaking, and residential proxy rotation; these performance and anti-bot claims are not independently verified here. Crawl results also depend on which subpages are accessible, while the hosted service is metered by requests. Pricing and free-use details are stated on the product site.
Before you try it
Its API can return Markdown, schema-based JSON, raw HTML and page screenshots. Choose structured extraction for fields or Markdown for source text, and inspect returned content before adding it to a dataset.
Official sourceThe publisher offers synchronous requests and asynchronous batch processing. For larger jobs, webhooks can deliver progress and completion payloads rather than requiring only interactive polling.
Official sourceThe pricing page says it bills successful HTTP 200 responses and does not charge for target timeouts or unresolved blocks. That billing policy is separate from whether a successful response contains the content your application expected.
Official sourceApify provides a marketplace and execution platform for Actors that collect web data and connect with applications or AI agents.

Gaffa controls cloud browsers through a REST API and can return screenshots, page content or Markdown. Credits depend on runtime, proxy bandwidth and optional processing, not request count alone.
Flatkey presents shared access to AI models and pay-per-run tools, with subscriptions, wallet top-ups, and custom enterprise routing and billing.

TalorData provides structured search-engine results through an API, with engine and location controls and pricing described as per successful response.

Diaform uses AI agents to run customer conversations by voice or text, with follow-up questions and response analysis. Plans meter AI messages, projects and team seats separately.

Buda is a cloud workspace for teams of AI agents with persistent files, tools and scheduled tasks. Plans distinguish basic agent chat and drives from browser, terminal and Git access.